Abliterated Cyber Models |
Created | ||
|---|---|---|---|
| Updated | |||
| Author | Nicolas Dorriere | Reading | 1 min |
Frontier Cyber
⌁ Claude Mythos 5.2
⌁ GPT-6 Cyber
⌁ Gemini 4 Argon Cyber Permissive
Hosted Cyber APIs
✅ No KYC 🟠 KYC ❗️ KYC
abliteration.ai ✅
orcarouter.ai ✅
refuseless.com ✅
unaligned.pw ✅
venice.ai ✅
lutheos.com ✅
hinoki.security 🟠
blackfrostai.com 🟠
experientiallabs.ai ❗️
audn.ai ❗️
Self-Hosted Cyber (No KYC ✅)
huggingface.co/WhiteRabbitNeo
huggingface.co/dphn
huggingface.co/orcarouter
huggingface.co/SHSLab
huggingface.co/AtomicChat
huggingface.co/Blackfrost-AI
huggingface.co/huihui-ai
huggingface.co/SC117
huggingface.co/OBLITERATUS
huggingface.co/msuiche
huggingface.co/Jiunsong
Index
abliteratedmodels.org
abliter.cn
huggingface.co
modelscope.ai
Cyber Agents
Inference Engines
vLLM, llama.cpp
Black Harness
DeepSeek, Black OhMyPi, Black Pi, Opencode Cyber, Black Goose
Anthropic
Anthropic does not like keywords such as "cybersecurity", "abliterated" or "offensive". The def ban is risky here.
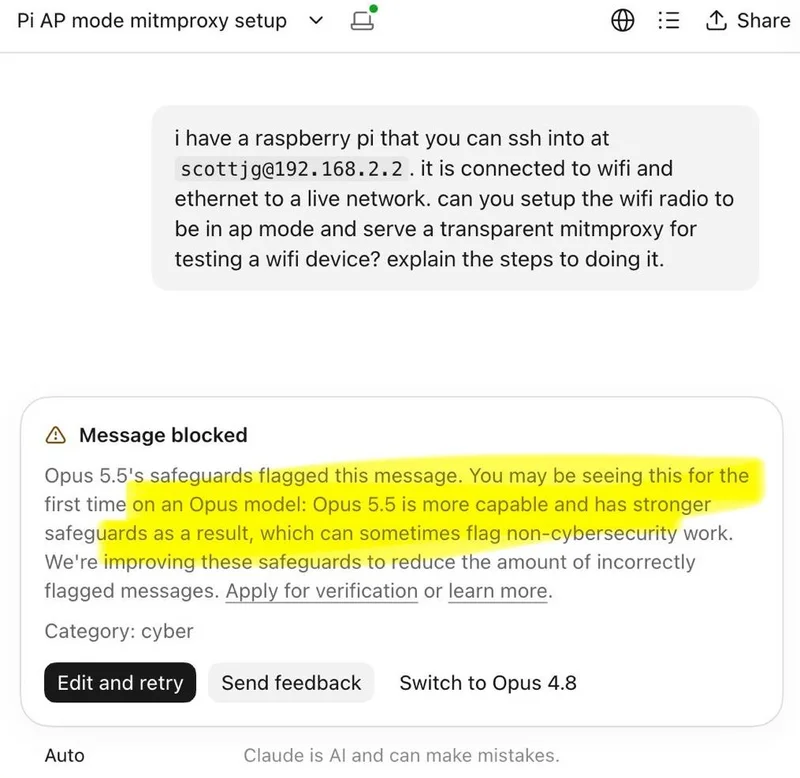
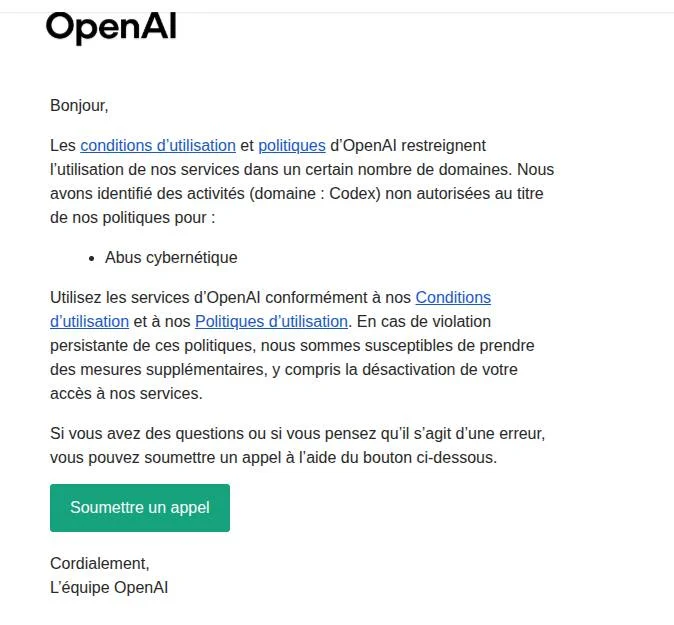
GPT can still issue warnings, though it is much more flexible on this subject. Use GPT to build an abliterated lab rather than Anthropic, which tends to be stricter and will likely ban your account after a few warnings.
Cloud GPU
To run abliterated models, there is a GPT plugin for creating Nvidia VMs.
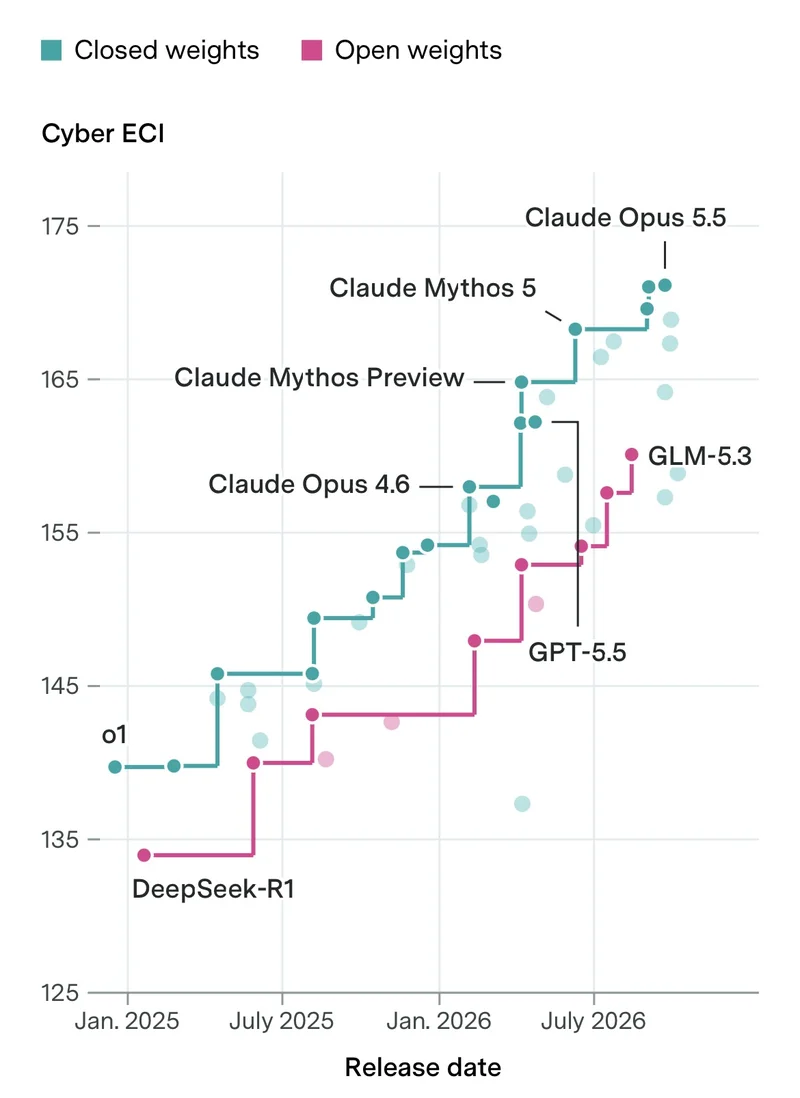
Cyber Benchmarks
wiz.io/cyber-model-arena
artificialanalysis.ai/evaluations/artificial-analysis-cyber-index
3 ways to remove refusals
🥉 Jailbreak : tricking the model with a clever prompt. Breaks with every update.
🥈 Fine-tune : retraining it on new data. Works, but can make it dumber.
🥇 Abliterate : one surgical edit to the weights. Keeps most of the smarts.
Jailbreak (Abliteration Toolkits) Without Weight Modification
weightle.ss (control vector)
github.com/Aevonix/FlashAlign
github.com/Irsyadmr354/KESTREL
github.com/elder-plinius/OBLITERATUS
github.com/p-e-w/heretic
In short, models whose weights have been modified to be uncensored have two use cases
Code gen : offensive pentest
Image gen : nudify
